
AI Searched
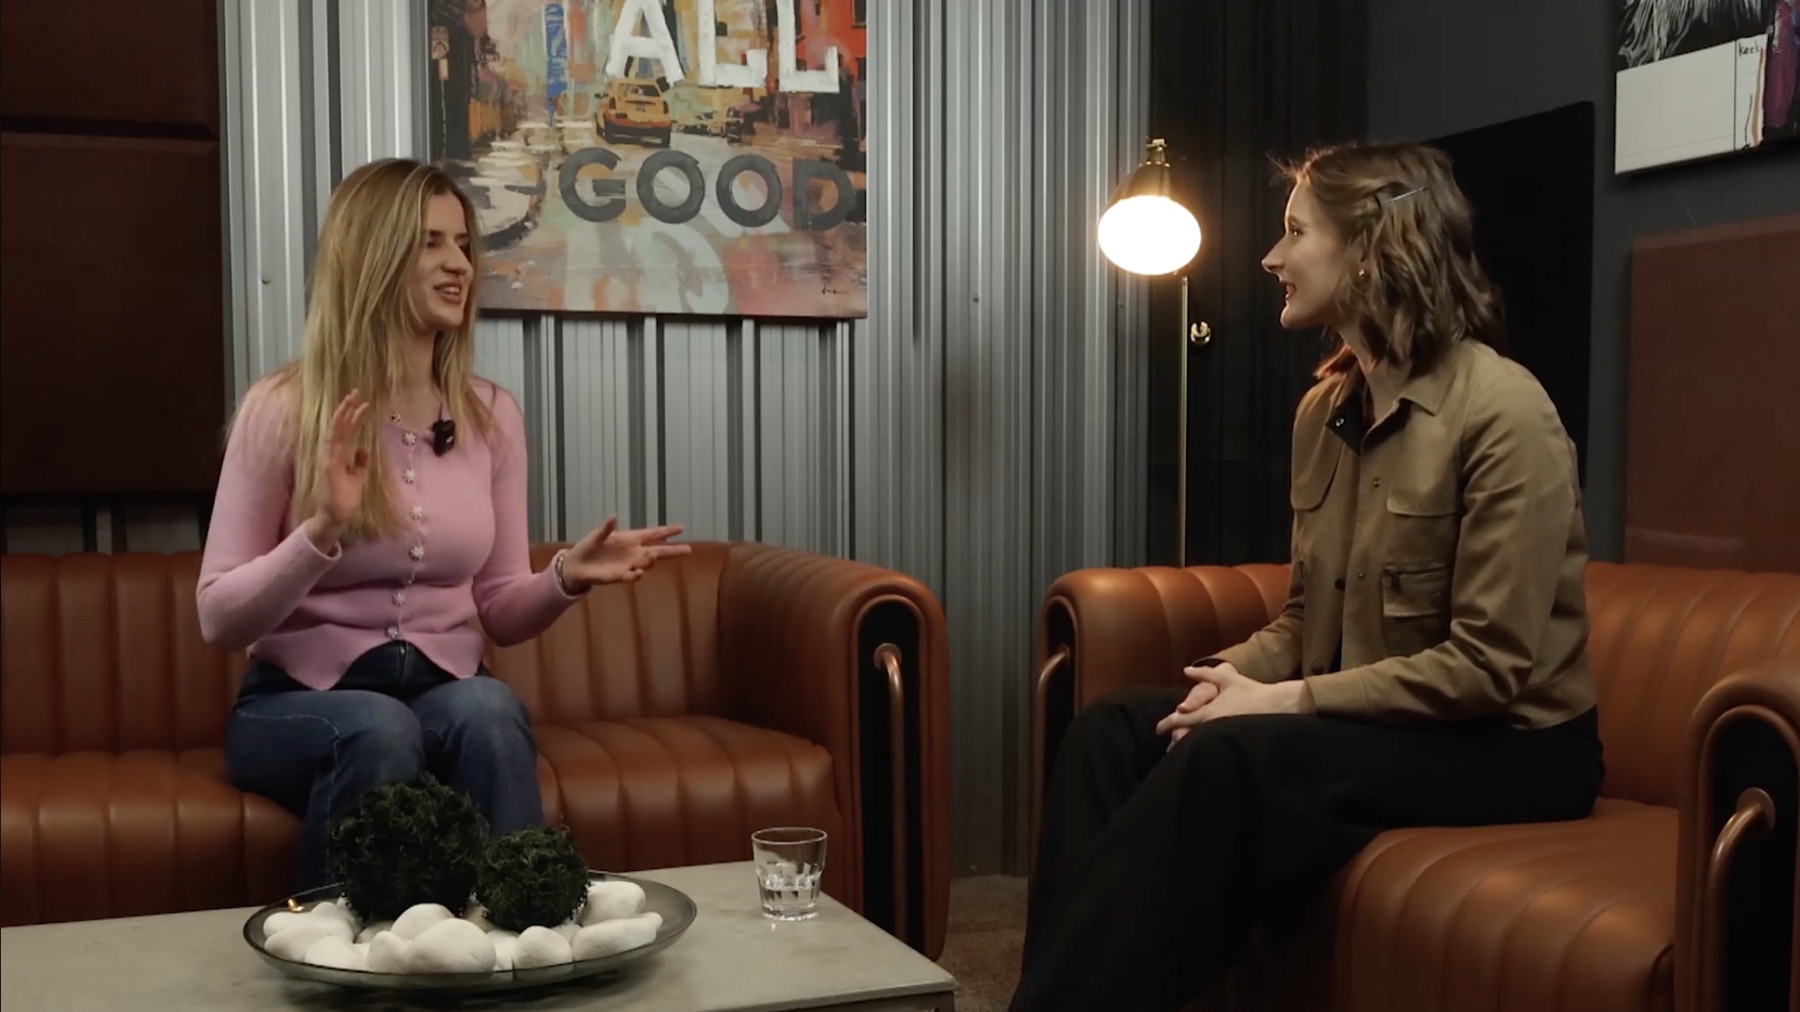
A weekly interview series on the business use cases of AI, running past thirty episodes. Every episode arrives as hours of multi-camera raw footage that has to become a captioned long-form cut, a set of vertical shorts and a searchable archive — with a two-person team and a weekly deadline.
Thirty episodes, two people, one weekly deadline
Each recording session produced several hours of multi-camera footage, B-roll and screen capture. Somebody had to watch all of it to find the moments worth cutting, then type captions by hand, then find those same moments again when a guest asked for a clip weeks later.
The editing timeline could scrub by time. It could not answer a question. Nobody could ask it which two minutes of episode 14 were worth a vertical short.
Hours of rushes per episode
Multi-camera footage, B-roll and screen capture, all of it needing a first pass by eye.
Captions typed by hand
Every long-form upload needed a caption track, written after the cut was locked.
Shorts picked on instinct
The best sixty seconds were found by memory, not by looking at the whole episode.
The archive was write-only
A guest asking for their clip weeks later meant re-watching the episode to find it.
From raw footage to a published short
One query against a single episode of raw footage. Pick a result to jump the player and the extraction log to that moment.
Captions are generated from the audio as the rushes land, so the long-form cut has a caption track before anyone opens the editor.
Speech recognised and time-aligned to the second, with speaker turns separated.
Caption track exported straight to the YouTube upload — no manual typing.
One pass over the rushes, four outputs
Omnisearch indexes each session’s rushes as they land. Speech becomes a caption track, every scene gets a description, each speaker is recognised and clustered across the whole series, and audio energy ranks the moments most likely to work as a vertical short. The producer opens a list of candidates instead of a three-hour timeline.
Ingest
Point Omnisearch at the session folder. Multi-camera rushes, B-roll and screen capture, as delivered.
Extract
Speech to captions, a description per scene, speaker recognition, and audio energy across the episode.
Rank
Candidate short segments scored by audio energy and speech density, cropped to 9:16.
Search
Every episode stays queryable, so a clip request is answered in seconds months later.
“The shorts used to be the worst part of the week. Now the episode lands, the captions are already there, and I am choosing between four clips instead of hunting for one.”
Every upload ships with a caption track nobody typed.
Four ranked candidates per episode instead of a three-hour scrub.
Guests recognised across all thirty-plus episodes, automatically.
Ship the episode, not the timeline.
Send us one episode of rushes. We index it, you search it, and you leave the call with the shorts already picked.