Underline Science
“Underline Science is the world’s first live-streaming and digital library platform for cutting-edge scientific and medical content. Our library includes over 50,000 video lectures from the world’s leading scientific conferences, and you can think of our product as the Netflix for researchers and professionals.”
Metadata search only reached a fraction of the library
Jernej shares that in addition to the size of Underline Science’s library, their content types are also diverse and heterogeneous. “Our library includes video lectures, slides, posters, textual content, metadata, and more. Our previous search functionality Algolia was a traditional one, with a focus on metadata like titles, descriptions, tags, etc. This only leveraged a small part of our content.”
Six content types, one library
Audio, video, papers, slides, posters and transcripts, each published alongside the lecture.
The recordings stayed dark
A researcher could find a session, but not the four minutes inside it that mattered.
Manual entry does not scale
Eighty thousand lectures cannot be described by hand, with new conferences landing weekly.
Search a 45-minute lecture, land on the sentence
A real query against one recorded webinar. Pick a result to jump the player and the transcript to that moment.
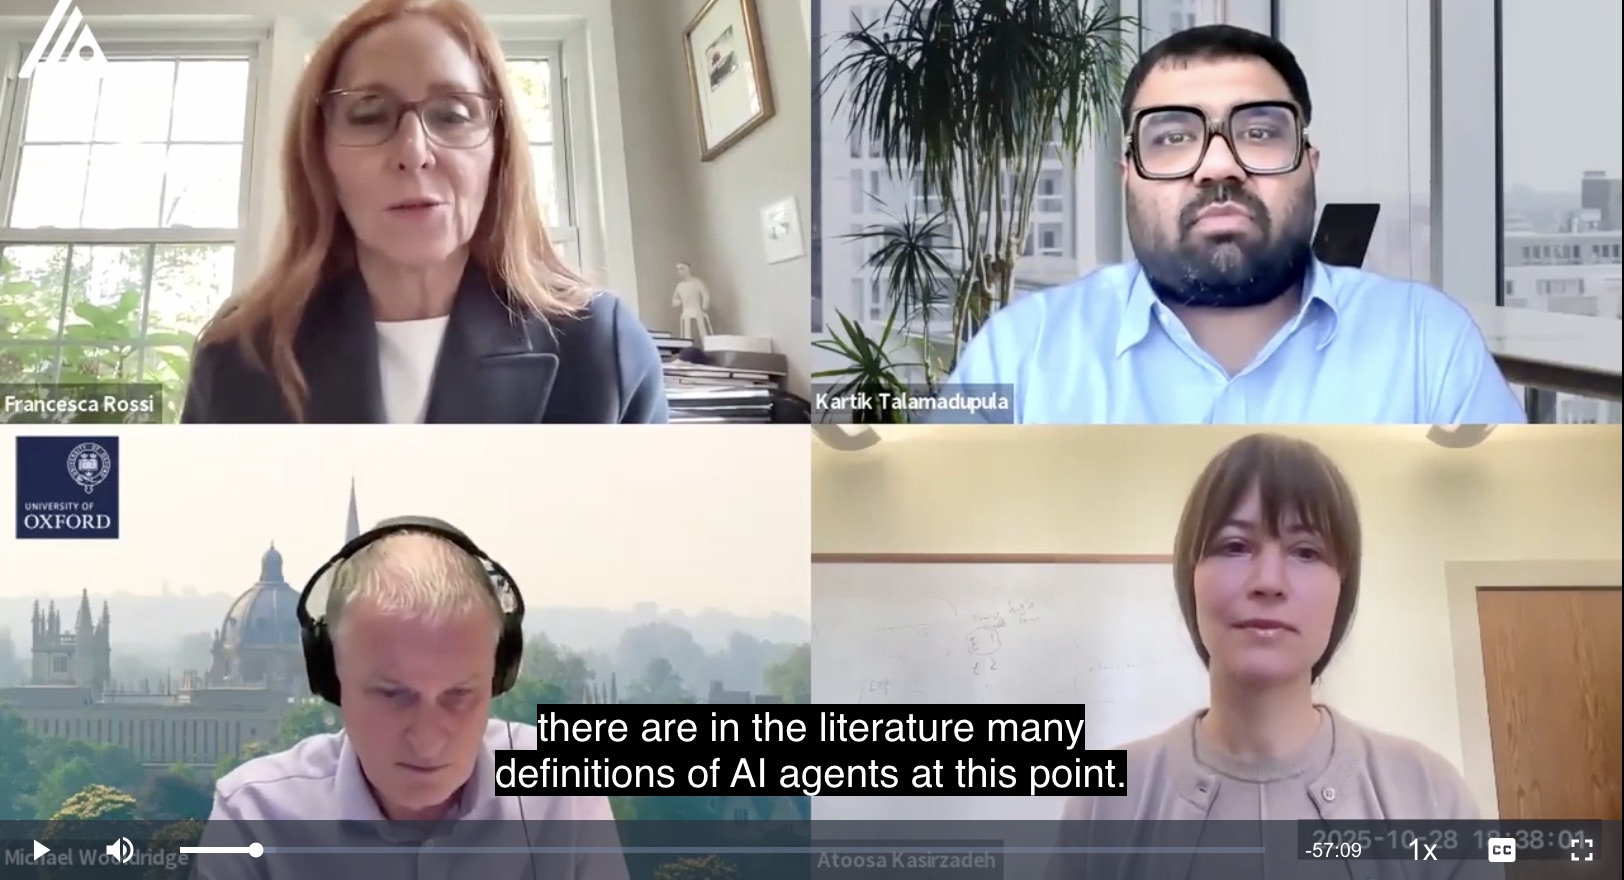
Atoosa Kasirzadeh closes on governance frameworks
“We use our knowledge over many decades of AI agents to define the governance, the right guardrails, and the evaluation methods that let us deploy these systems where the stakes are real.”
Every lecture indexed, no metadata entry required
Omnisearch was implemented in Underline Science in May 2022, and indexes all media content on the Underline Science library, without the need to manually type in metadata cues or text. Omnisearch’s audio processor recognizes spoken text on any language and creates an automatic searchable transcript and captions. Omnisearch’s tool allows users to search topics in videos, pictures, slides, and more, so they can find the most important content for them quickly and efficiently.
Ingest
Point Omnisearch at the existing library. No re-upload, no change to the publishing flow.
Extract
Speech to text in 50+ languages, on-screen text via OCR, plus faces and logos per frame.
Index
Every second of every lecture becomes addressable, alongside the metadata that already existed.
Search
A plain-language query returns the timestamp and the evidence that produced the match.
“In 2022 we found Omnisearch, which enabled us to index all our content and not just the metadata. Integrating it into our site allowed our users to search inside videos, transcripts, slides and documents. As a result we increased the number of item investigations by 70% and made our product much more usable for the end user.”
What Omnisearch brought
No one types a cue, tag or description by hand. The index builds itself from the recording.
Speech, on-screen text, faces and logos, each searchable on its own track.
New events index as they publish weekly, so the library never falls behind.
Your library could be the next story here.
Start with a free pilot on a slice of your catalog. We index it, you search it, then we talk numbers.